
Measuring Proficiency with Item Response Theory
Roxxem estimates each learner's language ability on a 1–10 scale, aligned to CEFR and ACTFL, from the games and activities they already do on authentic video rather than from a separate test. That ability can't be observed directly, only the learner's answers, and each answer depends on both the learner's ability and the question's difficulty. This post explains how Item Response Theory (IRT) separates the two and reports how certain each estimate is, and where it still falls short.
The problem: measuring from practice, not from tests
An exam controls who sees what; a learning app does not. Teachers assign different lessons, learners pick their own videos, and the app serves content near each learner's level. Our first version used a CTT-style score, after Classical Test Theory (CTT): percent-correct weighted by the expert-rated difficulty of the content. CTT treats a score as true ability plus random error that averages out over enough items. When every learner sees different content, that breaks down: the score ignores which items were answered, has the same error after three sessions as after thirty, ties item difficulty to who answered, and cannot flag misfitting items or learners.
The CTT-style score was the right starting point: it needs no response history, so it worked from day one, and every session it scored became data for calibration. As usage grew, these limits began to matter, and the current system moves to IRT, which models each response as a function of both learner ability and item properties, and so separates the two.
Content, tasks and items
Before we explain IRT, we need to define an item, the unit it measures. In Roxxem, an item is one piece of content played through one task. The same video can be an easy item in a word-recognition task and a hard item in a sentence-reconstruction task.

Figure 1. One video, four tasks, four items: Roxxem's current tasks. The content is described once, each task targets one skill, and the difficulty of each pairing is estimated from response data.
Each half is described on its own:
Content is described along ACTFL's performance criteria: discourse type (from words and phrases to full paragraphs and extended discourse), contexts and content (from familiar personal topics to concrete work-related and abstract ones), vocabulary (from high-frequency to specialized and precise), time frames, formality, and speech rate and dialect.
Tasks carry a fixed profile: one target skill, a response action, and the comprehension depth they can reach (word, phrase, sentence, paragraph). One skill per task keeps practice focused and each task's responses on a single ability scale.
Content still carries the expert-rated difficulty the CTT-style score used, but the IRT model ignores it. Difficulty belongs to the pair and is estimated from response data, as described in the calibration pipeline below. Tasks are designed for learning first, and a good item serves learning and measurement alike: one the learner can succeed at but might not. That is where practice stretches them and where each answer tells the model the most.
The measurement model
With items defined, we can turn to the model. Like TOEFL iBT, NWEA MAP Growth and the Duolingo English Test, Roxxem uses IRT to place learners and items on one scale. Our model is the two-parameter logistic (2PL):
- θ (theta) is learner ability.
- b is item difficulty: the ability at which the probability of a correct answer is 50%.
- a is item discrimination: how steeply that probability rises around b.
Figure 2 shows why discrimination matters. Both items have the same difficulty, but only the steep one separates learners just below b from those just above it.

Figure 2. Item characteristic curves for two items with equal difficulty. The steep item (high a) separates learners around b sharply; the flat item (low a) carries little information.
Because learners and items share one scale, a learner's θ does not depend on which items they saw, and an item's b does not depend on who played it. That addresses CTT's limits: learners are comparable even with no item in common, and difficulty reflects the item, not its audience.
Estimation
Each observation is one learner's session on one item, scored as correct answers out of total questions. Only a learner's first play of an item enters the fit, so learning from repetition is kept out. Items and learners are estimated jointly with Bayesian inference, one scale per language and skill domain. Every θ, b and a comes with a standard error (SE). For learners, it is reported as a confidence value from 0 to 1, computed as 1 − SE² and clamped to that range: the smaller the SE, the higher the confidence. A learner with three sessions is reported with lower confidence than one with thirty. θ converts to the Roxxem level, which maps to CEFR and ACTFL through a published concordance table.
Example. Two learners play the same video in the same task. The model expects the weaker learner to answer about 1 question in 10 correctly and the stronger learner about 7. If the weaker learner gets 6 right, the result is far better than expected, so their estimate rises sharply. If the stronger learner gets 9, the result is only slightly better than expected, so theirs rises a little. Each estimate moves in proportion to the surprise, and less as history builds.
Calibration pipeline
Learners build history over time, and so do items. A new item starts without parameters and acquires them as responses arrive. Items are recalibrated on a regular schedule, and each moves through a fixed lifecycle:

Figure 3. Item lifecycle. Items gain parameters as responses arrive; items that stop separating learners are flagged, then retired.
Until it has n_calibrating responses, an item is routed by its content properties alone. It then receives provisional estimates of difficulty b and discrimination a, and after n_calibrated responses it is fully used in estimation and selection. An item whose a falls below a threshold a_min is flagged and waits for more evidence. It returns to calibrated if a recovers, and is retired if it stays flagged for t_retire, so it stops affecting θ.
Low discrimination is also a design signal: an item that fails to separate learners often fails to teach too, because of an ambiguous question, a guessable answer or a poor fit between task and content. The reverse holds too: calibrated items that separate learners well accumulate into a pool of proven practice, which Roxxem recommends to learners near their level.
Validity
A model can be estimated well and still measure the wrong thing: IRT can fit cleanly while measuring reading speed or game skill. Validity is the degree to which evidence supports the intended interpretation of a score, here that a level reflects functional proficiency against the CEFR and ACTFL descriptors. We follow the argument-based approach of the Standards for Educational and Psychological Testing (AERA, APA & NCME, 2014) and Kane (2013).
Three kinds of evidence are in production. Content is tagged against ACTFL descriptors, and generated questions are reviewed by language experts before release. Every learner estimate carries a confidence value. Items with low discrimination, the flat curve in Figure 2, are flagged and retired.
Known limitations
Practice data meets the model's assumptions only in part.
- Correlated answers. Questions in one session share content, so treating them as independent understates the uncertainty on item parameters.
- Game effects. Power-ups and time pressure can move scores for reasons unrelated to language.
- Population shifts. A changing learner population can move the scale; re-centering keeps levels stable.
Next, we are extending the evidence in three directions:
- Fit and fairness. Check that items fit the model and work the same across languages, skills and grades.
- External agreement. Compare θ with placement results and teacher-assigned levels, and set level boundaries empirically through a standard-setting study with teachers.
- Learning impact. Measure whether level-targeted practice produces more growth.
What the level tells you
For each learner, language and skill, Roxxem reports a level from 1 to 10 with a confidence value, mapped to CEFR and ACTFL. Because all learners in a language and skill share one scale, the level supports comparing learners who practiced different content, tracking growth over time, and serving content near the learner's level, where input is comprehensible but stretching (Krashen's i+1) and items tell the model the most. Growth is reported as change in θ, so a gain reflects ability rather than an easier set of assignments.
The level is only as good as the history behind it. Practice data is broad but slow to accumulate, and a new learner has none. The next post covers the adaptive test that fills this gap: item selection, stopping rules, and how its items are generated and vetted.
How Roxxem Measures Proficiency
- Part 1: Measuring Proficiency with Item Response Theory (this post)
- Part 2: Inside the Roxxem Adaptive Test
Further reading
IRT foundations
- D-Lab, UC Berkeley. Introduction to Item Response Theory. https://dlab.berkeley.edu/news/introduction-item-response-theory
- Hambleton, R. K., Swaminathan, H., & Rogers, H. J. (1991). Fundamentals of Item Response Theory. (Chapter 1 compares IRT with Classical Test Theory.)
- Lord, F. M. (1980). Applications of Item Response Theory to Practical Testing Problems.
IRT in large-scale tests
- Manna, V. F., Li, S., Papageorgiou, S., & Gu, L. (2025). TOEFL iBT Technical Manual (ETS Research Report RR-25-12). https://rr.ets.org/index.php/etsrr/article/view/28/17
- NWEA (2026). MAP Growth Technical Report for 2024–2025. https://www.nwea.org/uploads/MAP-Growth-Technical-Report-2025.pdf
- Naismith, B., Cardwell, R. L., LaFlair, G. T., Nydick, S. W., & Kostromitina, M. (2026). Duolingo English Test: Technical Manual. Duolingo Research Report. https://go.duolingo.com/dettechnicalmanual
Validity and fairness
- AERA, APA & NCME (2014). Standards for Educational and Psychological Testing. https://www.testingstandards.net/open-access-files.html
- Kane, M. T. (2013). Validating the interpretations and uses of test scores. Journal of Educational Measurement, 50(1), 1–73.
Proficiency frameworks
- ACTFL (2024). ACTFL Proficiency Guidelines 2024. https://www.actfl.org/educator-resources/actfl-proficiency-guidelines
- Council of Europe (2020). Common European Framework of Reference for Languages: Companion Volume. https://www.coe.int/en/web/common-european-framework-reference-languages
Second language acquisition
- Krashen, S. D. (1985). The Input Hypothesis: Issues and Implications.

Pulse helps world language teachers track student progress on ACTFL and CEFR levels, spot skill gaps and pick the right lesson next, without a test day.
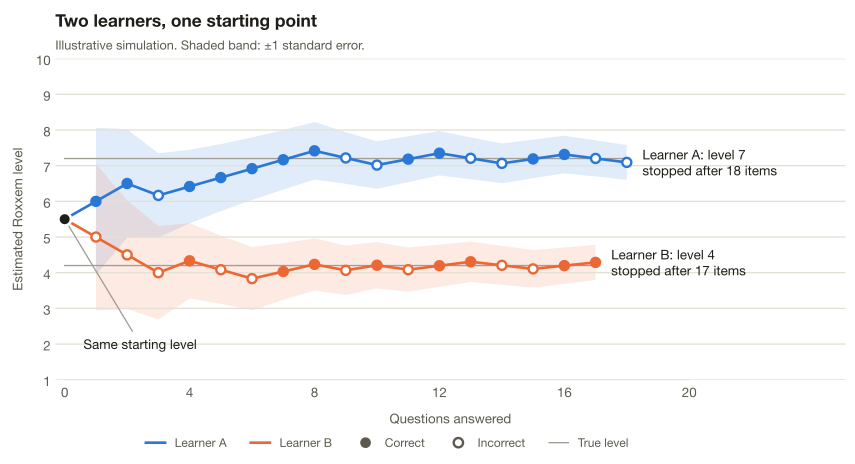
See how Roxxem's adaptive proficiency test places learners in about 10 minutes, and how we generate and validate its 10k-item bank with LLM evals.
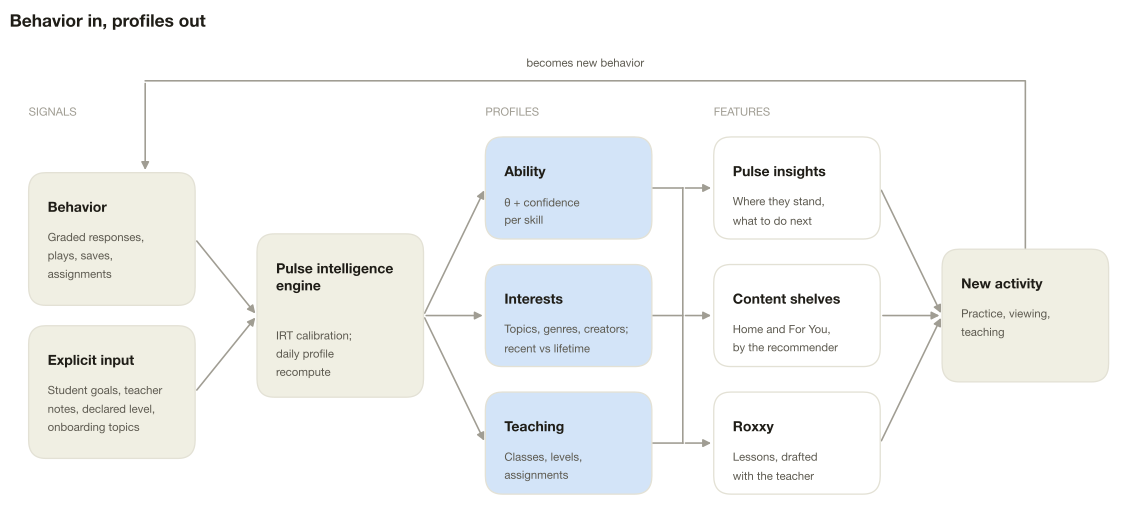
Profiles built from behavior and a recommender tuned for learning, not watch time: the tech foundation for personalized language learning at Roxxem.

Learn how Roxxem's new user proficiency scoring works, and how it fuels personalized learning and real-time feedback on our platform. The system adapts to how students learn and guides them to the next step.